§ About · Founder & Practice
Nine years between the sequencer and the paper.
I started PrimeOmicX because the labs generating the data rarely had one person who could build the pipeline, run the statistics and deploy the model. I spent nine years doing all three in academic and public-health research. PrimeOmicX offers that combination to labs and companies.
§ 01 / Principal
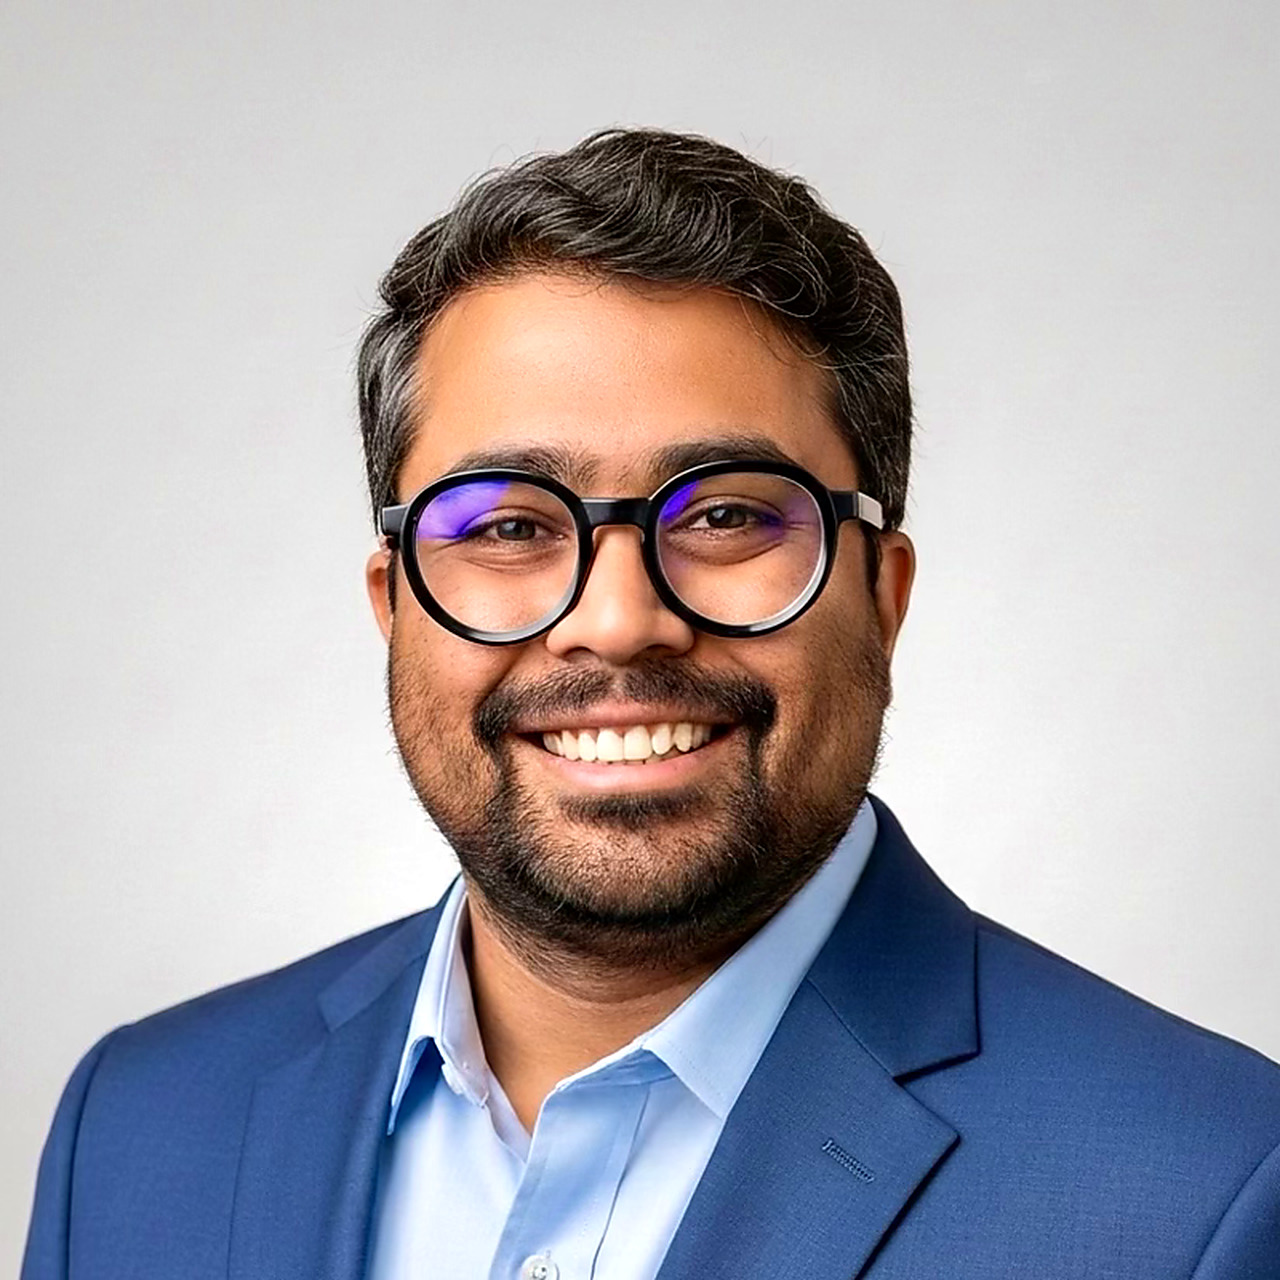
I have spent nine years on the computational side of life-science research: variant calling for NIAID's clinical sequencing initiative, single-cell immunology at Emory's National Primate Research Center through COVID, then four years at CDC building the surveillance pipelines behind national reporting. Eighteen peer-reviewed papers, including a co-first-author study in Cell. Since 2026 I work independently on pipelines, retrieval systems and small models.
§ 02 / Before PrimeOmicX
Before PrimeOmicX.
Work from the founder's earlier roles at NIAID, Emory and CDC, each with a public repository or published paper. It belongs to those institutions and is listed as professional background, not as PrimeOmicX engagements; naming them implies no affiliation or endorsement.
Aquascope
Principal architect of the national SARS-CoV-2 wastewater genomic surveillance pipeline, versions 1.0 to 3.1. Published in Emerging Infectious Diseases, 2025.
CDC · National Wastewater Surveillance System
github.com/CDCgov/aquascope ↗KIF5A plasma proteomics
Targeted plasma proteomics using the multiplex NULISA platform to uncover biomarker signatures in KIF5A-linked SPG10 and ALS spectrum disorders. Published in Human Genetics and Genomics Advances, 2026.
Emory School of Medicine · Pant Lab
PubMed: 40873038 ↗AIVA clinical benchmarking
Benchmarked agentic ACMG variant classification, co-authored the preprint evaluation study, and guided product direction and go-to-market strategy.
Mamidi Health
Preprint PDF ↗IMPACC immune transcriptomics
Lead bioinformatician on a 5,000-patient study across 15 centres; built the QC and processing pipeline on AWS with Snakemake. Cell Reports Medicine and Nature Communications.
Emory National Primate Research Center
Baricitinib in rhesus macaques
Co-first author on the Cell 2021 single-cell and CITE-seq study of lower-airway inflammation in SARS-CoV-2 infection.
Emory National Primate Research Center
Analysis code ↗Clinical exome pipeline
Whole-exome variant calling and automated QC for 1,200 clinical patients.
NIH / NIAID Clinical Sequencing Initiative
github.com/arunbodd/NIAID ↗tautyping-nf
Nextflow pipeline for selecting optimal phylogenetic markers in microbial genomes. Published in Bioinformatics, 2023.
Open source
github.com/arunbodd/tautyping-nf ↗
§ 03 / Principles
Working principles.
Held on every engagement, from the first line of code to the final manuscript figure.
- 01
One team, whole stack
Most groups do the analysis or the engineering. Here it is the same person, so the pipeline and the paper are built together and the models feed back into the analysis.
- 02
Reproducible by default
Every analysis ships as a versioned, containerised, tested workflow. Re-run it in a year and get the same answer.
- 03
Private by design
On-device models and on-prem retrieval mean patient, sample and IP data stay on machines you control.
- 04
Measured, not promised
Evaluation harnesses before models. Benchmarks before optimisation. Numbers in every report.
- 05
You own everything
Code, weights, documentation and infrastructure. No lock-in and no black boxes.
§ Direct Collaboration
Work directly with the founder.
One senior computational biologist accountable for the pipeline, the statistics, and the deployed model. Replies within two working days.
Schedule Scoping Intro →